
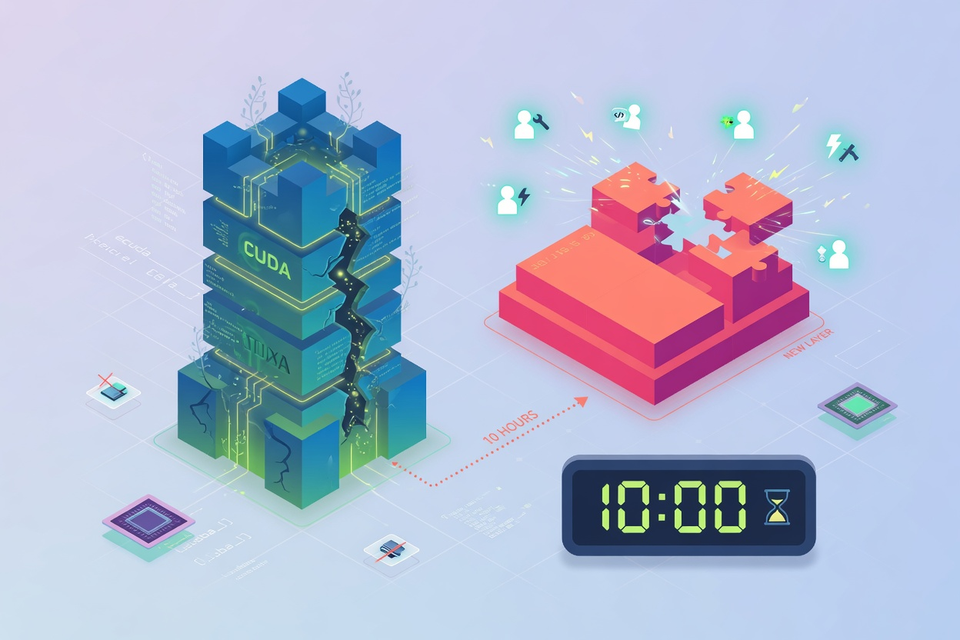
The most valuable thing Nvidia owns is not a chip. It is CUDA, pronounced KOO-duh, the software layer that two decades of programmers have learned, cursed at, and built their careers on. TheNextWeb reports that a one-year-old startup called Infinity used AI coding agents to rebuild the equivalent of that layer for a rival chipmaker in about ten hours. For scale, I have spent longer than that getting a printer driver to work.
Think of CUDA less as a product and more as a road network. Nvidia's GPUs are fast cars, but the reason nearly everyone buys them is that twenty years of roads, service stations, and maps already exist for them. A competitor can build an equally fast car and still lose the sale, because its customers would be driving through a field.
Infinity is the company claiming to pave those roads on demand. Founded by former Google Brain researcher Jeremy Nixon, it raised a 15 million dollar seed round at a 100 million dollar valuation, SiliconANGLE reports, with backing from Touring Capital and angel investors from OpenAI and Anthropic. Its agent, called Ignition, generates the unglamorous plumbing that makes a chip usable: compilers, debuggers, profilers, and the hand-tuned kernels that shuttle data around efficiently.
That ten-hour figure comes from work for d-Matrix, a maker of inference accelerators. Infinity says Ignition reached 92 percent of the Corsair chip's theoretical peak performance within those ten hours, and separately claims a 34 percent throughput gain over the standard vLLM software on one of Alibaba's Qwen models after a day of tuning. The scorekeeper matters here: Infinity ran its own benchmarks, no independent measurement has been published, and the company sells exactly the service those numbers advertise.
Why the excitement anyway? Because of where the market is heading. Training a model rewards staying inside Nvidia's ecosystem, where thousands of GPUs already cooperate smoothly. Running a finished model, the business called inference, rewards whoever does it cheapest, and that opens the door to any rival chip that suddenly has passable software. TheNextWeb quotes Marshall Choy of the Korean chip startup Rebellions saying that on the inference side, "CUDA is no longer a factor."
Cold water arrives in the same reporting. Generated code still has to be verified, which remains the slow part. Writing the code is a fraction of shipping production software, and chip-level programming is a niche craft with few public examples for a coding agent to learn from. An afternoon of generated kernels is not twenty years of battle testing.
Still, the shape of the threat has changed. Nvidia has outlasted every challenger that built a faster chip, because the fight was never really about the chip. If coding agents keep improving, the expensive part of competing with CUDA stops being expensive, and this challenger is not a company that can stumble or get acquired. It is a workflow, and workflows only get cheaper.


Leave a Reply